AP invoice automation, end to end
A mid-size distributor moves 4,000 supplier invoices a month from a shared Google Drive folder into their ERP. This is what that looks like in IDPForge — every decision, in order, including the ones that go wrong.
- Situation — 4,000 invoices/month filed into a shared Google Drive folder, keyed by hand into Coupa by three people.
- Goal — 80%+ straight-through delivery, with a review loop for the rest that two people can hold.
- Uses — Google Drive source · Split / Classify · AP Invoice v3 schema · cross-field rules and per-field thresholds · Post Processing exit webhook · one review queue
- Outcome — 83% straight-through in week 6. Average handling 3.4 min on the remainder.
The shape of the problem
Northwind's AP folder is not clean. A single PDF might carry an invoice, its packing slip, and a statement of account. Around one in nine files is not an invoice at all — credit memos, remittance advice, and the occasional signed contract. Any design that assumes "one file, one invoice" fails in the first week.
So the pipeline is built around the split, not around the extract.
Step 1 — Point the source at the folder
Northwind's clerks already filed every supplier PDF into a shared Google Drive folder, and the scanning station saved there too. Rather than change that routine, Northwind connected the AP team's Drive account in Settings → Integrations and bound it on the pipeline's Source stage, with AP/Inbound as the input folder. Processed files move into a processed/ subfolder, so the input folder doubles as a visible backlog.
Web Upload stays on alongside it, so the API submissions the procurement team also sends keep arriving, and each job records which source it came from.
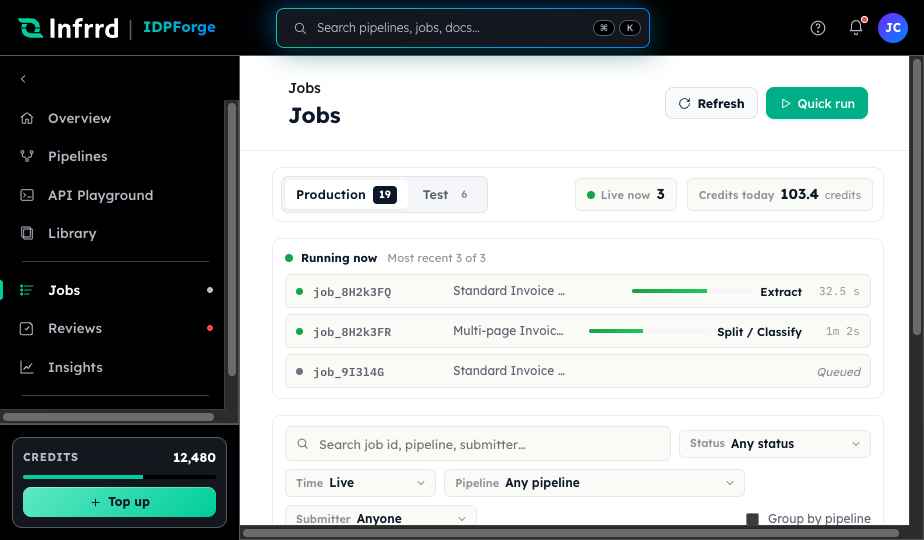
Once the folder is bound, jobs appear in Jobs and you can watch each one cross stages.
Step 2 — Split before you classify
Split runs first and cuts a 6-page PDF into three documents. Only then does Classify assign each one a class from the taxonomy: FIN.INV, FIN.CM, LOG.PACK, FIN.STMT. The routing rules for packing slips and statements bind no schema, so Extract runs on them in generic mode — captured for the record, not held to an invoice schema.
Because the class of a package is meaningless. Classifying before splitting produced a 62% accuracy ceiling in Northwind's first attempt — the model was asked a question with no correct answer.
Step 3 — One schema, bound to one class
Only FIN.INV routes to AP Invoice v3: 14 header fields and a line-item table. Credit memos get their own schema. The temptation to build one big schema with optional fields was resisted — optional fields make every confidence score mushier, because the model cannot tell "absent" from "missed."
Step 4 — Validation lives in the schema
Validation runs inside Extract, against the schema, and it catches more than the confidence scores do:
| Check | Catches | On failure |
|---|---|---|
Cross-field rule total == subtotal + tax | Missed charge, OCR digit slip | low_confidence_extract → review |
Per-field thresholds on total and bank_account | A plausible-looking misread | Field flagged needs_review → review |
Northwind's first design also had a vendor-master lookup and an open-PO check. IDPForge does not validate against master data, so those two checks stayed in Coupa's own invoice-approval rules, where the vendor and PO records already live.
With Send exceptions to Reviews turned on for Extract — it is off by default — any of these becomes a review task instead of flowing straight to delivery.
Step 5 — One queue, not five
Turning on the review toggle provisioned one queue for the pipeline, "AP invoices · Review." The instinct is a queue per exception type. Northwind kept one, narrowed it to the FIN.INV and FIN.CM document classes, and set its SLA to four hours. Two operators work it. Splitting into five queues would have created five ways to be idle while a sixth pile grew.
Northwind turned the same toggle on for Split / Classify, so an uncertain cut (split_boundary) or an uncertain class (low_confidence_classify) lands in the same queue as the extraction exceptions.
Step 6 — Deliver through a webhook
Coupa is not a built-in destination, so Northwind's own integration does the last mile. It is bound to the Post Processing stage's exit webhook; on each delivery it checks the signature, pulls the result from the Job Results API, and posts the invoice to Coupa. Web Response is always on, so nothing else had to be configured on the Destination stage.
Step 7 — Coverage that shrinks
Week one, every correction is verified: each operator starts at the seeded Flat 100% review coverage while the team learns what "correct" means for these documents. By week six, Flat coverage is 10% with two rules held at 100% — any invoice whose extracted total is at least $50,000, and every credit memo. A new operator joins at Flat 100% and is dialled down deliberately.
What went wrong
- Faxed invoices broke the split — A handful of suppliers still fax, and the scanning station saved those pages dark and grainy. The split model cut mid-invoice, and with review off on Split / Classify the bad cuts flowed straight into Extract. Fixed by turning on Send exceptions to Reviews for Split / Classify: most of the fax cuts came back below the 0.7 boundary-confidence line and now wait for a person.
- Duplicate postings after a Coupa outage — Coupa timed out for 40 minutes. Northwind's integration had posted some invoices before it failed and returned an error, so IDPForge retried those webhook deliveries and 19 invoices posted twice. The integration now records each delivery id and document id before posting and ignores repeats.
- The 0.80 default threshold was too generous on bank details — A supplier's new bank account number was extracted with one digit wrong at 0.88 confidence. That was above the 0.80 default, and no cross-field rule can check an account number, so nothing flagged it and a payment bounced. Fixed with a per-field threshold of 0.97 on
bank_accountandtotalin the schema.
Where it landed
| Metric | Before | Week 6 |
|---|---|---|
| Straight-through rate | — | 83% |
| Documents touched by a human / month | 4,000 | 680 |
| Average handling time | ~6 min (full key-in) | 3.4 min (correction only) |
| People on AP entry | 3 | 2, part-time |
Extraction accuracy was good on day one. What took six weeks was getting the routing and the validation rules right — which is where almost all IDP projects actually spend their time.